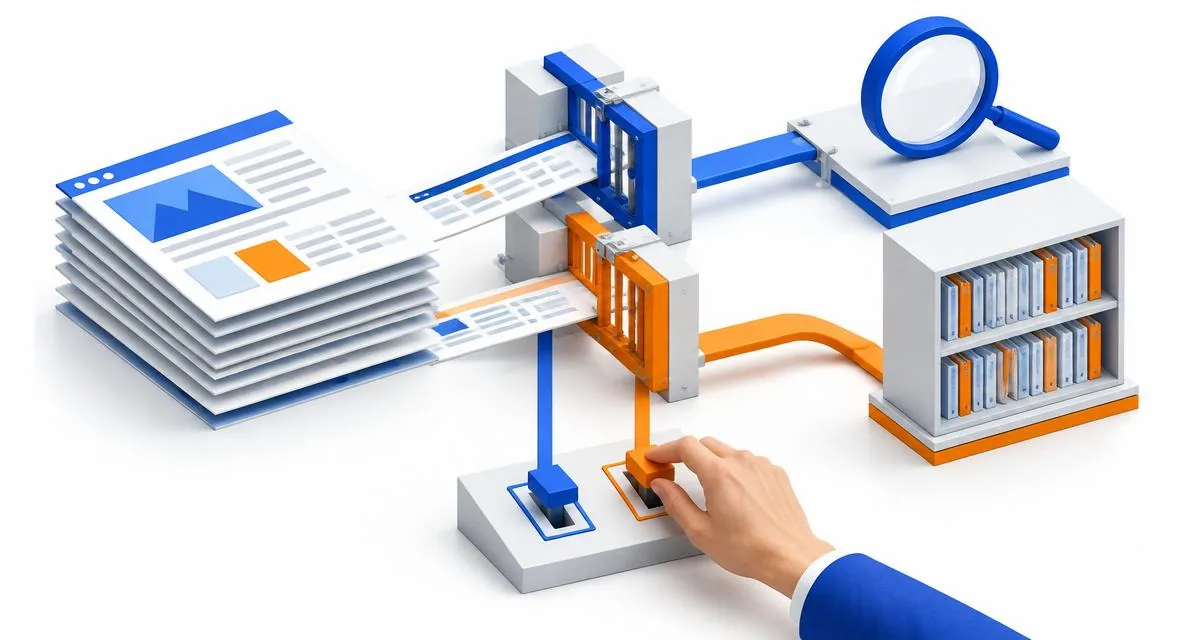
Is allowing AI search the same as allowing training?
Not necessarily. Some providers publish separate controls for search discovery and potential model-training use. Website owners should review the documented purpose of each crawler rather than make one blanket assumption about all AI bots.
The official crawler documentation linked below explicitly separates search and training permissions for its crawler family. That is provider-specific guidance, not proof that every assistant uses the same controls or follows the same policy.
What does search-crawler access allow?
A search crawler retrieves public material to support the documented search experience. Allowing access can make retrieval possible; it does not force inclusion, a favorable answer or a recommendation.
Search foundations still matter: accessible content, understandable service information and accurate identity. Official AI-search guidance says there are no additional special requirements for the features it describes. Existing SEO is not replaced by a separate AI file.
What does a training preference control?
A training-related rule expresses the documented preference for a particular crawler or service. Its scope comes from current provider documentation. It is not a universal contract, an access-control system or proof that material has never appeared in another dataset.
Review whether search, user-directed retrieval and training are governed separately. Do not copy a bot list without checking the business goal. Policies and agent names can change; a documented owner should keep the decision current.
Can robots.txt keep confidential pages private?
No. Crawler instructions are not authentication. Sensitive material needs appropriate access protection. Official search guidance also distinguishes blocking crawling from removing a page from an index: a blocked URL can still be known through other links.
If search exclusion is the goal, the appropriate method depends on the content and system. A noindex directive must be accessible to the crawler that needs to read it. A technical administrator should review the consequences rather than blocking an entire site reflexively.
Why might a permitted crawler still fail?
Robots permission does not override a firewall, a login requirement or an unsuccessful page response. Review what the intended crawler can actually retrieve, including important text and source links. A successful browser visit alone does not establish every crawler’s experience.
Keep security controls in place. Investigate the specific legitimate crawler and its verified documentation rather than weakening protection broadly. Retrieval, indexing and a later citation remain separate states.
What is the business decision?
Identify which public content you want discoverable and what training preferences you want to express. Review those choices against publishing rights and contractual obligations. Record the purpose of any approved change and check its actual effect.
This article does not change DigitalOS’s crawler policy. For the broader context, read our AI-answer eligibility guide or explore AI Visibility. No access rule guarantees traffic or an AI citation.
Sources and limitations
Reviewed November 4, 2026. External findings are not DigitalOS experiments or guarantees. Practical recommendations are DigitalOS guidance; research, products and policies can change.
- Official search and training crawler controls
Living product documentation. Independent search and training permissions apply to the documented crawler family, not every AI system.
- Official AI-search eligibility guidance
Living product-specific guidance. Established SEO practices remain relevant; eligibility does not guarantee inclusion.
- Official robots.txt introduction
Explains crawl control versus index exclusion. Product-specific instructions; robots.txt is not a confidential-data protection method.